Unified Agent Memory — Case Study
Coding agents forget everything between sessions.
Overview
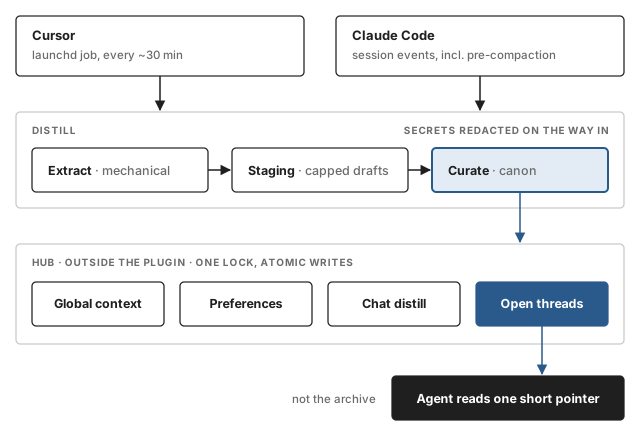
Coding agents forget everything between sessions, and the default fix — more context, more retrieval — makes them slower, costlier and leakier. Agent Memory takes the opposite bet: memory is an editorial problem, not a storage problem. Over 23 releases it became a routed working memory shared by Cursor and Claude Code, where machines draft, a human makes canon, and the agent reads one short pointer instead of the archive.
Three questions drove every release: what should the agent see, who is allowed to make it canon, and how do we know it was used.
The problem
Coding agents start every session blank. Project rules help inside one repo, but they do not carry what actually compounds across work: cross-project conventions, approaches already rejected, the distilled shape of long threads, and where we stopped yesterday across five checkouts.
The obvious fix — load the transcripts — fails on three counts. It is slow, it is expensive in context, and it leaks secrets by default.
Reframe. I treated memory as an editorial desk, not a vector store. The job is to route a small, correct slice to the agent at the right moment: read the index first, choose a layer explicitly, rotate content out when a layer hits its size limit.
My role and constraints
I owned the whole loop: the product model, the information architecture of the hub, the distill pipeline, the plugin code, migrations and releases. No PM, no separate engineering team — so every design call had to survive its own implementation cost.
The constraints that shaped the work:
- Two host environments with different contracts. Claude Code fires real session events; Cursor dropped hook support mid-2026 and can only run on a schedule.
- Public repo, private data. The framework is open source; the memory it holds is personal and must never leak.
- Zero ops. No database, no hosted service, no embedding pipeline to maintain.
- Context is the scarce resource. Every token the agent reads from memory is a token not spent on the task.
Principles
Four principles did most of the deciding. I borrowed them from design-system practice, where tokens, components and pages stay separate for the same reasons.
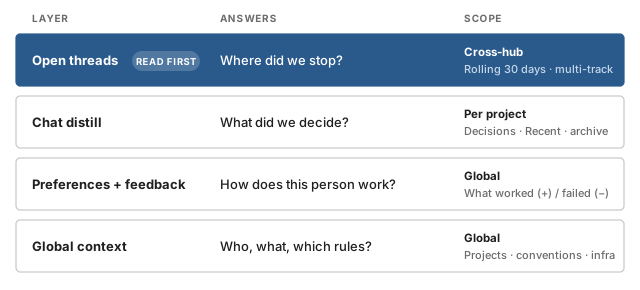
- Route, don’t dump. Each layer answers one question. The agent reads the index and picks a layer; it never loads the hub.
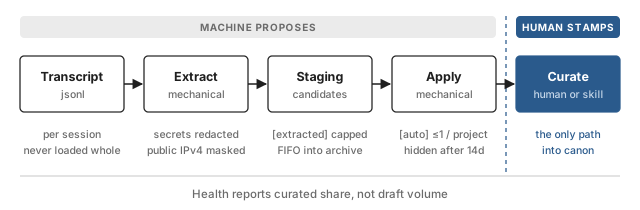
- Machines draft, humans stamp. Automation can propose. Only curation makes something canon.
- Session fitness over completeness. A short, correct pointer beats a complete, stale archive.
- Measure use, not writes. A metric that rewards volume will be optimised into noise.
Key decisions
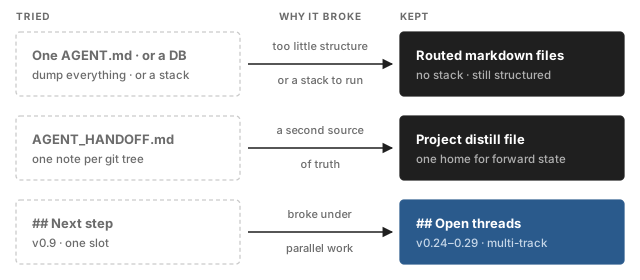
Most of the version history is a sequence of deliberate rollbacks. Each decision below names what I tried first, why it broke, and what I accepted in exchange.
1. Layers instead of a dump
Context. Agents given the whole memory read none of it well.
Decision. Split memory into layers that each answer one question, entered through an INDEX. Open threads is the forward pointer and is read before Decisions and Recent.
Cost. The agent needs routing discipline every session, enforced through skills and rules.
2. Routed files instead of one AGENT.md — or a database
Context. Three architectures competed: a single markdown the agent always loads; a set of files with an INDEX and layers; or something heavier — a database, embeddings, a service to keep running.
Decision. The middle path. Markdown files in a hub: structured enough to route, simple enough to audit and diff, with no stack to stand up. Effectiveness had to come from editorial structure, not from infra.
Cost. Weaker paraphrase recall than a vector store. The system stays local, inspectable, and cheap to run.
3. Distill-first, not a handoff file per repo
First attempt. An AGENT_HANDOFF.md in every git tree. It looked humane.
Why it broke. It created a second source of truth that drifted from the hub.
Decision. Forward state lives in one place: the project’s distill file.
4. Open threads replace a single Next step
First attempt. One ## Next step line — the landing-page CTA of memory.
Why it broke. Real work forks into parallel tracks; one slot forced the agent to forget the others.
Decision. ## Open threads: multi-label, a 30-day window, visible across the whole hub.
Cost. Harder to keep tidy than one line, and harder for the agent to choose from.
5. Staged curation instead of auto-summaries
First attempt. Full automatic summaries written straight into durable Decisions. They scored badly.
Decision. A staged contract: extraction and staging are mechanical; semantic merge and pointer curation are where meaning becomes canon. Guardrails keep drafts in their place:
[extracted]entries are capped, with FIFO rotation into the archive[auto]Open threads never overwrite curated ones — at most one per project, hidden after 14 days
Cost. A staging backlog and real semantic-merge work.
6. Two writers, one hub
Context. Cursor lost hooks mid-2026 and runs continuity on a periodic job. Claude Code still fires session events, including one before context compaction.
Decision. Environment modules feed one shared hub through the same lock and atomic writes.
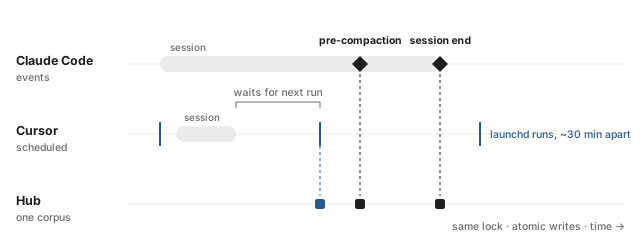
Cost. Uneven freshness: Cursor can lag by one cron interval. The corpus stays single.
7. Privacy by construction
Decision. Secrets are redacted at distill time; public IPv4 addresses can be masked. A push-time leak gate derives personal names from the local hub rather than from a denylist in the public repo — that list would itself be the leak. Framework tests use fictional project names only.
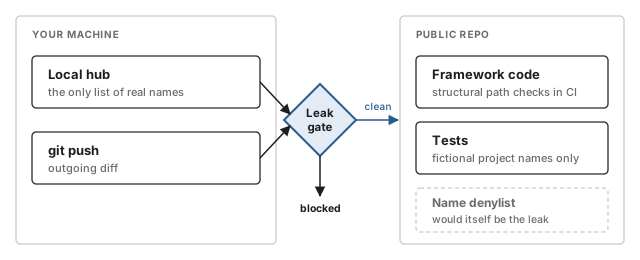
Cost. CI without a hub is weaker on names; structural path checks still run everywhere.
8. Search without a database
Decision. Given files, search stays on files: BM25-lite over markdown, with archive and optional deep extracts at lower weight. No embeddings, no external service.
Cost. Weaker paraphrase recall. In return: full auditability and zero ops — enough for “what did we decide?” and “where did we stop?”
Measuring trust
I replaced coverage with two narrower signals, because a dashboard full of green drafts would have taught me to optimise drafts.
- Curated share. Health reports how much of memory is human-curated, not how much the extractor produced.
- Pointer effect. Did the agent actually use what memory surfaced in that session?
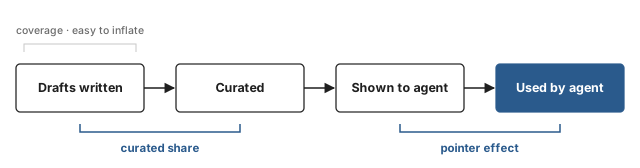
If the metric lies, the team optimises the lie. A narrow honest signal is worth more than a broad flattering one.
Open question for this case study: add the current curated share and pointer-effect rate, plus one before/after number from the auto-summary period.
Trade-offs at a glance
| We chose | We paid |
|---|---|
| Small layers and routing | Skill and rule discipline every session |
| Curation over full automation | Staging backlog; semantic-merge work |
| Multi-track Open threads | Harder to maintain than one Next step |
| Shared hub, two triggers | Uneven freshness between Cursor and Claude Code |
| Routed markdown files (not one AGENT.md, not a DB) | No stack to run; weaker semantic recall than embeddings |
[auto] as draft only |
Noise unless capped: one per project, hidden after 14 days |
What it is now
Not perfect agent memory — a working desk for a human and a model. The machine casts drafts, curation stamps canon, and the agent reads a short pointer instead of the archive.
Open threads is the only forward pointer; everything else is read on demand.
Reflection
The system got better every time I removed something that looked helpful: the per-repo note, the single Next step, the auto-written Decisions. Each one was a reasonable first answer that failed under real, parallel, multi-environment work.
What transfers beyond this project:
- Information architecture is the product. For agents, what is read first matters more than what is stored.
- Trust needs a contract, not a model. Staging plus explicit curation made automation useful instead of noisy.
- Privacy belongs in the build, not the policy. A denylist in a public repo is the leak it was meant to prevent.
- Honest metrics shape honest systems. Measuring use instead of writes changed what I built next.
Source on GitHub · Unified Agent Memory on Work
Unlisted · noindex · not on the Work grid · framework ~v0.31